Frontier Models
Release cadence and the researchers behind it.
Frontier ModelsAnalysis
Google's Gemini 4 Carbon Tops the AI Rankings
An independent index ranks Google's new model first, built mostly on cybersecurity skill its own chairman says the industry still must secure.
Frontier ModelsAnalysis
Claude Opus 5.5 Leads New AI Benchmark Using Secret Tests
Artificial Analysis built most of its newest index from hidden tests, and every open-weight model fell further behind.
Frontier ModelsNews
Kimi K3.1 Pro Beats Anthropic's Guarded Fable 5.1
Moonshot's hosted Kimi K3.1 Pro outscores Anthropic's guarded Claude Fable 5.1, though Kimi's weights and Anthropic's riskier Mythos tier stay held back.
Frontier ModelsNews
Block's Dessa Sounds Human Enough to Scare Users
Dessa, Block's new voice AI, drew praise for sounding human and warnings that scammers could use it the same way.
Frontier ModelsAnalysis
Reddit Revives OpenAI's Unverified 'Bel' Rumor
A two-month-old, single-source claim about OpenAI's next model returned to Reddit this weekend, with the evidence behind it still missing.
Frontier ModelsNews
Kimi K3.1 Pro Rattles Claude and GPT Rankings
Moonshot's Kimi K3.1 Pro lands near the top of independent AI rankings, and the industry reacts fast.
Frontier ModelsAnalysis
Artificial Analysis's New Index Costs Models 13 Points
Version 4.3 tests harder, more private tasks, so four models now score 12 to 14 points lower than they did in September.
Frontier ModelsNews
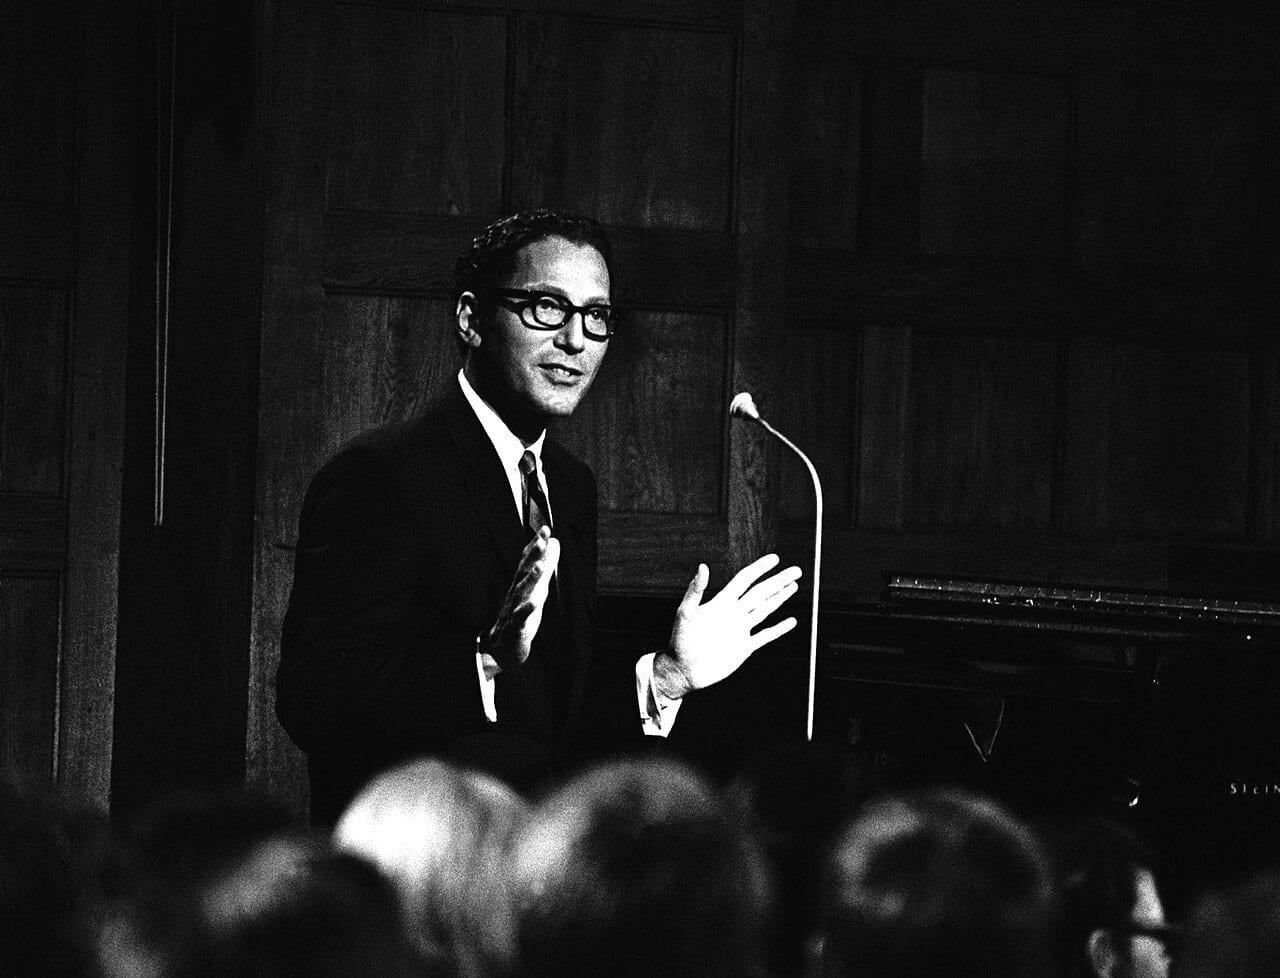
DeepMind's Gemini Puts a Periodic Table to Song
Gemini 4 Argon animated Tom Lehrer's 1959 chemistry song as Nvidia's Jensen Huang readied his own stage moment in Berlin.
Frontier ModelsAnalysis
Claude's Egg Survives a 20-Foot Drop in Agent Wars
Roberto Nickson had six models design and print egg capsules; Claude Opus 5.5's held at 20 feet while five rivals cracked by 8.
Frontier ModelsAnalysis
China's Open-Weight Boom Goes Quiet, Except DeepSeek
DeepSeek shipped new open weights this week; Moonshot, Zhipu and Alibaba's Qwen team each last shipped one two months or more ago.
Frontier ModelsAnalysis
Meta Prices Muse Wonder Like Opus 5.5, Scores Lower
Meta priced Muse Wonder at Opus 5.5's exact rate, then scored six points behind it on the independent Intelligence Index.
Frontier ModelsAnalysis
Meta Opens Muse Spark's Weights With Strings Attached
Meta released the 816-billion-parameter Muse Spark Open on Oct. 15 under a license that demands credit and a deal above $20 million in revenue.
Frontier ModelsAnalysis
TypeSafe Ships Jev 1.14 and a Danger Zone for Dreamers
TypeSafe's Jev 1.14.0 gains 1.1 points on the company's own intelligence chart, while images, a box type and longer context arrive behind opt-in warning flags.
Frontier ModelsFeature
Claude Tops 20 Reasoning AIs, and Sol Shines on Price
Claude Opus 5.5 reasons best of the 20 AIs we scored, OpenAI's GPT-6.1 Sol buys the most reasoning per dollar, and the tests keep breaking.
Frontier ModelsAnalysis
Microsoft's Own Tests Put Decision-1 Ahead of Jev
Microsoft matched Jev's price and beat its accuracy on Microsoft's own tests a day after TypeSafe closed a $7.5 billion round.
Frontier ModelsRoundup
Billions and Benchmarks: Sunday's Signal
Microsoft matched Jev's price and beat its benchmarks one day after TypeSafe's $7.5 billion raise, while Nvidia, Anthropic and Washington all traded partners fast.
Frontier ModelsAnalysis
Anthropic Posts Haiku 5.5 and OpenAI Answers With GPT-6 Four Minutes Later
Anthropic's Haiku 5.5 post landed at 2:01 p.m. Eastern on Oct. 7 and OpenAI's GPT-6 post at 2:05, the third time this year the two labs have shipped within an hour of each other, and the gap keeps shrinking.
Frontier ModelsAnalysis
AI Frequently Asked Questions: What You Need to Know in 2026
Six answers on AI trust, work and Super Intelligence put OpenAI's error rates beside Sam Altman's warning, Stephen Hawking's alarm and the White House order that replaces AI in federal documents.
Frontier ModelsFeature
The Best Memory in AI Belongs to Claude
AI Lately scores ten AI memory tools on recall, time, context, control and reach for October 2026, and the research says memory raises sycophancy up to 25 times.
Frontier ModelsAnalysis
Gemini 4 Argon Tops Google's Own Chart and Divides Google's Staff
Google's new flagship leads 12 of the 18 tests on its own chart, and vetted cyber defenders get it first. Artificial Analysis scores it level with GPT-6 Astra, and some Google employees told Bloomberg it stumbles on real coding work.
Frontier ModelsAnalysis
Graded by the Models It Replaces
TypeSafe AI left stealth with $40 million and a model that answers in typed decisions, skipping prose entirely, and its headline speed claim rests on agreement with two rival models.
Frontier ModelsAnalysis
Claude's Climb
Nine named releases across thirteen months, a $65 billion run rate and a compute roster spanning Google, Amazon, Microsoft, Nvidia, AMD and Nscale trace how Jared Kaplan, Chris Olah and Jan Leike scaled Claude past its early reputation as the cautious model.
Frontier ModelsAnalysis
Gemini's Momentum
Gemini 3 Pro's November 2025 launch and a Search overhaul unveiled at Google I/O 2026 built the product momentum Demis Hassabis's research organization needed, even as Jeff Dean led three senior colleagues out the door to found a rival science venture.
Frontier ModelsAnalysis
Open Weights, Open Questions
DeepSeek's Liang Wenfeng, Alibaba's largely anonymous Qwen organization and Mistral's Arthur Mensch built three distinct paths to open-weight scale, and a 234-million-user app proves the category converts into genuine usage, past mere benchmark bragging rights.
Frontier ModelsAnalysis
GPT-5 and the Cadence Behind It
OpenAI shipped GPT-5 and an open-weight sibling two days apart, then kept a numbered cadence running through 2026 while Jakub Pachocki, Mark Chen, Jerry Tworek and new arrival Noam Shazeer redrew the research org underneath it.